10 minute read
Quick Answer
Bringing data from different sources together to create a consistent, reliable view across the organization. Data harmonization reconciles data from different sources into 1 consistent model, so the same entity means the same thing wherever it appears. The work runs in 5 steps, starting with the sources and ending with ongoing maintenance.
The second step tends to decide success, since that is where every source maps to a shared model. Ask 2 teams how many active trials you're running, and you may get 2 different answers. Each team reads from its own source, and each source defines a trial differently. Neither number is wrong, which is what makes the gap hard to close.
For a Chief Data Officer (CDO), the decision is where to start. Fixing formats source by source helps for a while, and 1 shared model tends to be what keeps those fixes in place. Datavid (a C5i company) builds that model around 1 use case at a time, so results arrive before every system is mapped.
At a glance
- Many harmonization problems come from meaning rather than format, so cleaning alone may leave them in place.
- Harmonization includes standardization and integration, then adds agreement on what each value means.
- A shared model recorded as an ontology tends to keep harmonized data consistent as sources change.
- 6 techniques cover most of the work, and the right mix depends on how the sources differ.
What is data harmonization?
Data harmonization is the process of standardizing and integrating data from disparate data fields, formats, and dimensions. It aims to improve the quality and usability of data, and can be accomplished in 5 steps.
Data harmonization enables users to access clean, consistent data, thereby minimizing complexity. Researchers writing in Scientific Data describe 3 dimensions the work has to resolve, and a project that fixes only 1 of them can still leave sources that disagree.
- Structure: how fields and tables are organized in each source.
- Meaning: what each value refers to, since 2 sources can use the same label for different things.
- Format: the technical format each source uses, such as CSV or JSON files.
The output is harmonized data, with 1 definition per entity across every source. That's the data harmonization meaning many teams care about, since 2 teams asking the same question can get the same answer.
Data harmonization vs data standardization vs data integration
Data standardization fixes formats within a field, so every date or unit follows 1 rule. Data integration moves data from several sources into 1 place.
Harmonization reconciles meaning across those sources and usually includes both, so planning it into the same pipeline as integration can save you a second project later.
| Aspect |
Data standardization |
Data integration |
Data harmonization |
|
What it changes |
Formats and values within a field |
Where data lives and how it flows |
Structure, meaning and format across sources |
|
Scope |
1 field or dataset at a time |
The pipelines between systems |
Every source behind a use case |
|
Output |
Values that follow 1 rule |
Data from many systems in 1 place |
1 comparable dataset with shared definitions |
|
Example |
Every date written as YYYY-MM-DD |
Trial and safety data loaded into 1 warehouse |
"Adverse event" defined once across studies |
How does data harmonization work? The 5 steps
Data harmonization is a semi-automated process that involves a set of activities customized to a specific business model.
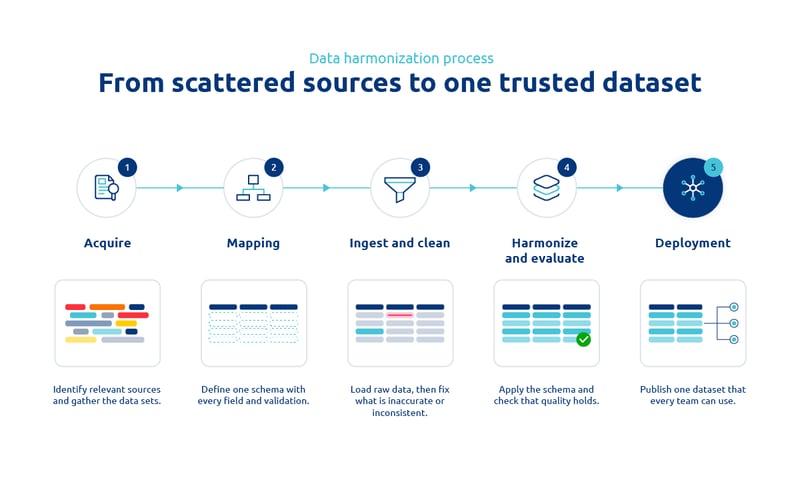
The process usually has the following steps, each with an output a CDO can review before the next one starts. In practice, the order matters most between steps 2 and 3, since cleaning against an unagreed model tends to create rework.
Step 1: Acquire
Start by identifying the sources your use case depends on and who owns each one. From those sources, data is acquired, and data sets are created. The output is a source inventory listing each system, its owner, and its formats. Cataloging every system in the enterprise first can stall the work for months.
Step 2: Map to a shared model
Business and data owners agree what each entity means and how entities relate, then record that agreement as an ontology. "Patient" in a trial database and "subject" in a safety system may need to resolve to 1 entity. Teams that map straight to field names may find the same label still carries 2 meanings after cleaning.
The output is a governed target model that each source maps into. With ontology management in place, a ruling on which definition wins is recorded once and reused. If you're weighing an ontology or taxonomy, let the use case decide, since a taxonomy groups terms while an ontology also records how they relate.
Step 3: Ingest and clean
Data is ingested in a system as raw data. Ingested data is then evaluated for its integrity and validity. Incorrect, inaccurate, or inconsistent parts of the data are identified according to the shared model and corrected where needed. Cleaning is done to maintain data quality and produce clean, uniform, and consistent data.
Log every change against its source record, along with the rule that triggered it. Without that log, a corrected value can look identical to an original one. The output is clean data you can trace back when an auditor asks why a value changed.
Step 4: Harmonize and evaluate
Now the defined model is applied to raw data and harmonized data is obtained. Analyses are done to check that the harmonized data meets the quality standards with no loss in its accuracy and originality. Check results against source records as well as the schema. The output is harmonized data with provenance, showing each value's source and the rule that changed it.
Step 5: Deploy and maintain
Finally, harmonized data is deployed on the system and made available for further processing. This up-to-date data is accessed across all parts of the organization and can be modified according to the need. Now teams and departments don’t have to develop their own datasets, which are likely to be expensive and error-prone.
Many projects stop at deployment, yet a renamed code or a new study can break a mapping. The output is a maintained data product with a named owner and checks that rerun on each change.
Data harmonization techniques and when to use each one
Each technique fixes a different kind of mismatch, and many projects combine several. Some deal with how data is laid out, such as field names and units. Others deal with meaning, such as which code refers to the same real thing. For a CDO, knowing which ones a use case needs helps size the work early.
Schema mapping
Schema mapping aligns the fields in each source with the target model, so a birth date stored as DOB in 1 database and birth_dt in another maps to 1 attribute. Use it when sources hold the same facts in different layouts, as often happens after a merger.
Vocabulary and code mapping
Local codes are mapped to standard vocabularies or a common data model. In observational health research, the Observational Medical Outcomes Partnership (OMOP) Common Data Model lets sites analyze their data together. It tends to matter most when sources use local codes for diagnoses or products.
Unit and value conversion
Units and dates are converted to 1 standard with the rule recorded, so a lab value in mg/dL at 1 site and mmol/L at another becomes comparable. Use it when sources come from different countries or instruments, and keep the original value for checking.
Entity resolution and deduplication
Entity resolution decides when 2 records describe the same compound. Knowledge graphs, a core part of Datavid's semantic work, can hold those links so an internal code and a trade name resolve to 1 entity. It's worth prioritizing when duplicates inflate counts, such as 1 customer appearing 3 times across systems.
Variable derivation and recoding
When sources measure different things, a comparable variable is derived from each. Smoking recorded as yes or no in 1 study and packs per day in another can share 1 agreed category. Use it when pooling studies that ask similar questions in different ways.
Rule-based and AI-assisted mapping
Rules handle the cases you already understand, and models propose the rest. People review low-confidence matches, and each decision is logged for audit. Use it when the volume is too large for manual work, such as thousands of local codes.
Why harmonized data matters for analytics and AI
Data in the organization comes from various sources. When each source defines the same entity differently, reports can disagree and a CDO may spend meetings reconciling numbers instead of acting on them. The cost tends to grow with each new source, since each one brings its own definitions.
1 answer per question. When R&D and regulatory teams read from the same model, a question about open trials can return 1 figure. Leadership can then act on the number instead of debating which report is right.
Lineage an auditor can follow. Each value keeps its source and the rule that changed it, so inspection evidence can come from the data itself. For regulated teams, that can mean answering an auditor's question with a query instead of weeks of manual tracing.
Data AI can reason over. AI systems don't stop to ask what a label means, so meaning needs to be explicit. Harmonized data is a large part of what makes data AI-ready, and a semantic layer can serve it to analytics and AI tools from 1 model.
Data harmonization best practices that catch problems early
Many problems in the data harmonization process surface after the data is combined, when 2 reports disagree or an auditor asks where a value came from. Each of these 6 practices moves a check earlier, while a fix is still cheap. For a CDO, they apply whether the team needs to harmonize data from 2 sources or 20.
Start from the question the data has to answer
Start by clearly defining your business objectives and the requirements for data harmonization. Then scope the work to 1 use case and the decision it supports, such as a safety signal review. An enterprise-wide inventory can take months before any data is harmonized, while a scoped use case gives leadership a result to review. Its definitions then become the starting point for the next one.
Agree definitions before you transform anything
Format problems tend to show up in testing, while disagreements about meaning can survive cleaning and reach a report. A trial team may count a patient as enrolled at consent while finance counts them at first dose. Settle what each core entity means, and who rules on conflicts, before anything is transformed. Record each ruling in the shared model so the debate isn't reopened.
Record every mapping decision
Document each mapping with its rule and approver, so the next team can see why each value looks the way it does. Findable, accessible, interoperable, and reusable (FAIR) data is the goal the FAIR Guiding Principles set out in 2016. Without that record, a mapping may live in 1 engineer's head and need rebuilding when that person moves on.
Validate against the source as well as the schema
A dose stored in the correct field with the wrong unit can pass a schema check. Sample records from each source and trace them back to the original value and the rule that changed it. These spot checks tend to catch the errors that look right in a dashboard and wrong in an audit, so rerun them whenever a mapping changes.
Govern access and change from day 1
Harmonized data is shared data, so role-aware access and change control are worth building into the design. Permissions applied in the model's layer can check each read the same way, whether it comes from an analyst or an AI assistant. A new definition can also ripple into every report that reads it, so route changes through an owner who approves them.
Treat harmonization as ongoing
Sources change after go-live, so the model and each mapping need a named owner. A system upgrade or a renamed field can break a mapping without anyone noticing until a report looks wrong. AI data management can support this with automated checks that flag a broken mapping, paired with a regular review of the model.
Data harmonization examples from clinical and R&D data
Roche and Syngenta both started from a shared model and mapped each source into it. The projects sit in different parts of life sciences, with clinical trial forms in 1 case and decades of research records in the other. Datavid delivered both, and the figures come from each case study.
Clinical trial data: 1 semantic model across studies
The Roche Helios program is a clear case of clinical data harmonization. Study-specific case report form (CRF) and non-CRF data were mapped into a common semantic model, with ontology-based checks automatically validating the mapping. The approach can support clinical trial management, in which each new study maps to existing definitions.
The reported results were 5x faster trial data processing, an 80% reduction in manual errors, a 40% reduction in operational costs and on-demand audit readiness for the US Food and Drug Administration (FDA) and European Medicines Agency (EMA).
R&D knowledge: vocabularies harmonized across 70 years of records
Syngenta's Synapse platform brought more than 70 years of R&D records into 1 searchable knowledge base. Regulatory vocabularies were harmonized across global standards and internal taxonomies, so a search on 1 term can find documents filed under another. The result was more than 16 million searchable documents, with retrieval taking minutes instead of 2 to 3 weeks.
Data harmonization tools and solutions: where each one fits
Many data harmonization solutions combine several categories of tools. The question for a CDO is which one holds the shared model, since the other tools tend to depend on it. A clear answer can keep definitions out of individual pipelines and dashboards.
|
Tool category |
What it handles |
Where it tends to stop |
|
Extract, transform and load (ETL) pipelines |
Moving data between systems on a schedule |
Meaning sits in code, so definitions can drift |
|
Master data management (MDM) |
Golden records for core entities |
Usually covers a few master entities |
|
Open-source clinical mapping tools |
Mapping clinical data to OMOP |
Scoped to health data |
|
Semantic data platforms such as Datavid Rover |
The ontology, mappings, and lineage in 1 layer |
Needs agreed definitions upfront |
Master data harmonization through MDM can work well for a few core entities. Across many domains, a semantic data platform can hold the shared model other tools read from.
Start data harmonization with a shared model
Many harmonization projects already move and clean data well. The step teams often skip is the shared model, and that gap may be why harmonized data drifts apart after launch. It's also the step that makes each subsequent source cheaper to add, because the definitions are already agreed upon.
For a CDO, the practical move is to start with 1 use case, then let that model carry the next source. Datavid's senior-led teams can deliver a first pilot within 6 to 8 weeks, with ISO 27001 and Cyber Essentials Plus certification.
Not every use case needs the entire data model. See how much of the model your first use case requires and where to focus your efforts.